

Anyone running several coding agents in parallel eventually hits the same wall: rate limits. Claude Code, Codex, and Cursor each burn through provider quota fast once you're running more than one session, and stitching together free tiers across a dozen different providers by hand — different SDKs, different auth, different limits — is its own chore. OmniRoute is built around that specific problem: a single gateway endpoint that fronts 290+ AI providers, tracks which free tiers you actually have quota left on, and falls back automatically when one runs dry.
The problem is not only inconvenience. When an agent hits a limit halfway through a refactor, you lose the session's context, your time, and sometimes a half-applied change you now have to untangle. Paying for higher tiers everywhere fixes that, but the cost adds up quickly as inference spend scales with agent usage. A gateway that pools capacity across providers is one answer, and OmniRoute explained in detail shows how much engineering that answer actually needs.
This article covers what OmniRoute does, how its three-layer failure handling works, the CLI and deployment options, the multi-engine token compression pipeline, its security architecture, and the self-hosted versus hosted decision that matters most before you adopt it.
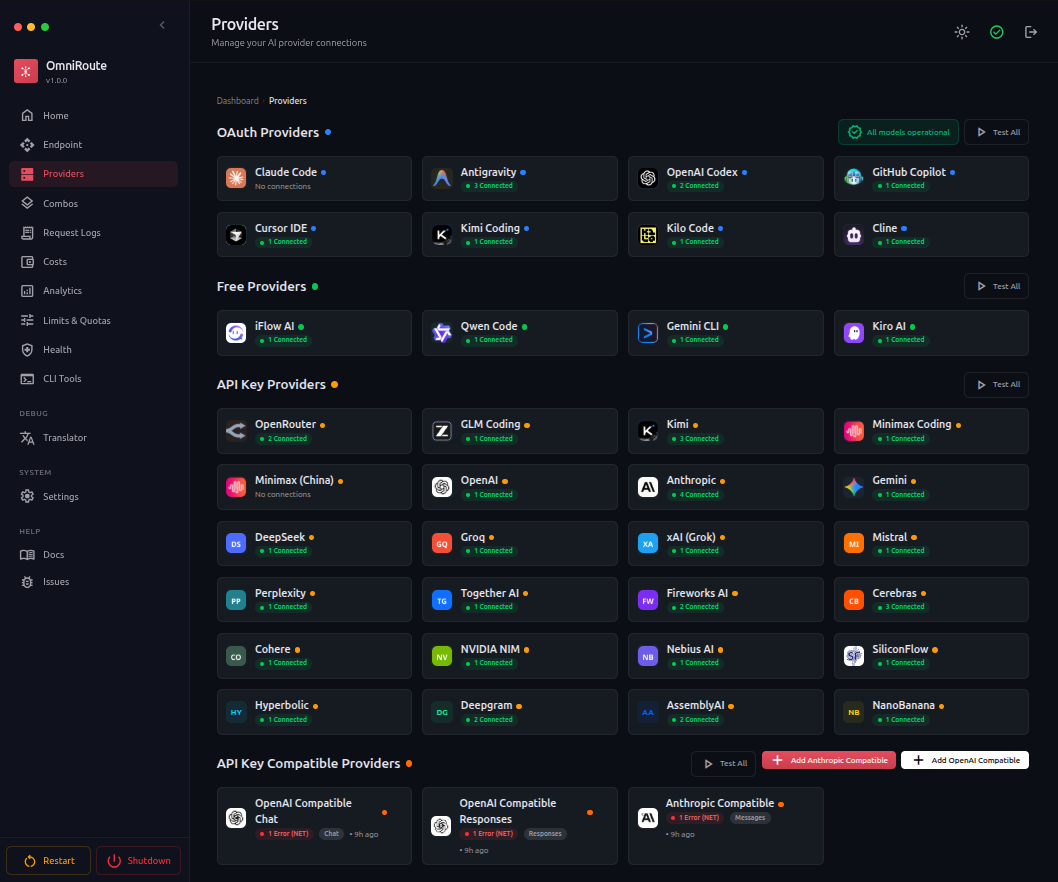
What It Actually Does
OmniRoute sits between your coding agent and the model provider as a proxy that speaks the API shapes those tools already expect, so Claude Code, Codex, Cursor, Cline, Copilot, and similar tools can point at it as a single endpoint instead of being configured against each provider individually. From there it handles the parts that get tedious to manage by hand:
- Quota-aware routing across providers. It tracks documented free-tier limits across dozens of provider pools and routes a request to one with capacity remaining, falling back automatically rather than surfacing a rate-limit error to the agent mid-task.
- Token compression. A layered compression approach (the project calls it RTK + Caveman compression) is applied to requests to reduce token usage, which matters directly for anyone paying per token on the providers that aren't free.
- 19 routing strategies. Beyond simple failover, the routing layer supports multiple strategies for how to pick a provider for a given request — useful when cost, latency, and specific model capability all pull in different directions for different tasks.
- MCP and A2A support. It exposes itself as an MCP endpoint and supports agent-to-agent protocols, so it plugs into an existing agent tooling setup rather than requiring a bespoke integration. If agent-to-agent communication is new to you, our explainer on the Agent2Agent protocol covers what that layer is for.
Failure Handling Is Three Separate Layers, Not One Retry Loop
The routing logic doesn't just retry blindly when something fails — the documented resilience model splits failure handling into three independent layers, each scoped to a different blast radius. A provider-level circuit breaker trips only on 408s and 5xx responses, with thresholds that vary by how you're authenticated (three failures for OAuth, five for API-key auth, two for local providers), and resets through a half-open probe rather than snapping back to fully trusting a provider that just failed; while it's open, the combo reroutes to the next provider automatically. Below that, a connection-level cooldown handles a single failing key or account — exponential backoff with jitter against thundering-herd retries, honoring a Retry-After header when a provider sends one, with success clearing the error state — so one cooling-down key doesn't take sibling keys in the same pool down with it. The narrowest layer is per-model lockout: a 429, a local 404, or a mode denial locks out just that specific model rather than the whole provider connection. Splitting failure handling this way is a meaningfully more careful design than a single global retry-and-fallback loop, since it means one bad model or one expired key doesn't have to escalate into abandoning an entire provider.

A Real CLI Sits Behind the Gateway
Beyond the HTTP endpoint, OmniRoute ships a command-line interface with a wide command surface — omniroute serves the gateway and dashboard, omniroute chat opens an interactive terminal chat client, omniroute setup runs a guided first-run wizard, and omniroute doctor diagnoses provider, port, and native-dependency problems. A remote mode extends the same CLI to control a gateway running elsewhere: omniroute connect <host> exchanges a password for a scoped access token saved locally as a named context, after which commands like omniroute models list or omniroute configure codex run against that remote server instead of localhost. Tokens can be minted with read, write, or admin scope for different machines, and process-spawning routes stay loopback-only regardless of how the CLI is connected — a reasonable constraint given what a misconfigured remote-controlled gateway could otherwise do.
Deployment Options Go Well Beyond a Single Server
OmniRoute is built to run in more places than a typical self-hosted gateway. A global npm install (npm install -g omniroute) works on any OS; a multi-arch Docker image supports both AMD64 and ARM64, which extends to Raspberry Pi and other ARM servers; an Electron build produces a native desktop app with a system tray on Windows, macOS, and Linux; and it runs on Android through Termux with no root required, intended to stay running continuously on a phone. It's also installable as a PWA directly from a browser for an offline-capable, installable experience without any of the above. Package-manager installs are available too, including pnpm and an Arch Linux AUR package that registers a systemd user service. That range matters less for a typical single-developer setup than it does for anyone trying to keep one gateway instance available across several machines and platforms without standing up separate infrastructure for each.
Token Compression Is a Multi-Engine Pipeline
The "RTK + Caveman compression" framing undersells the scope of what's actually running: token compression is implemented as a twelve-engine pipeline, and RTK and Caveman are two named engines within it alongside others including LLMLingua-2 (running as a MobileBERT ONNX model for learned, content-aware compression) and additional engines for structural and glyph-level compression. Output styles and an adaptive dial give per-request control over how aggressively compression is applied, rather than a single fixed setting applied uniformly to every request regardless of content. The practical implication is the same as before — lower token costs on any provider billed by usage — but the mechanism is a stack of purpose-built compressors rather than one general-purpose trick.
The Security Architecture Is Worth Actually Reading
For a tool whose entire job is sitting between your coding agent and the model providers it talks to, what matters most isn't the feature list — it's how seriously the project treats the traffic and credentials passing through it. On that front, OmniRoute's documented security model is genuinely substantive: a request pipeline that runs through CORS checks, an authorization pipeline, and guardrails that include PII masking and prompt-injection detection before hitting rate limiting and circuit breakers. Authentication covers JWT-based dashboard login, HMAC-signed API keys, and OAuth 2.0 with PKCE across 13 supported provider integrations. The repository also runs secret-scanning and container-vulnerability tooling as part of its CI pipeline — the kind of engineering discipline that's easy to skip and genuinely reassuring to see present in a project handling API credentials.

Self-Hosted vs. the Hosted Endpoint
This is the decision that actually matters most before adopting it, and it's worth being deliberate about rather than defaulting into whichever path the quickstart nudges you toward. OmniRoute is MIT-licensed and fully open source, which means self-hosting it is a real option, not just a theoretical one — running your own instance means your agent traffic and credentials never leave infrastructure you control. Using the maintainer's hosted endpoint instead is faster to get started with, but it means routing your coding agent's prompts and provider credentials through a third party's infrastructure, which is a meaningfully different trust decision than running open-source code you've reviewed on your own servers. Treat that choice the way you'd treat it for any proxy sitting in front of API credentials: self-host for anything you wouldn't want to depend on someone else's uptime and trust model for.

OmniRoute vs Connecting Agents Directly to Providers
The alternative most developers start with is pointing each coding agent straight at one provider, then adding accounts or upgrading tiers when limits bite. Comparing the two setups makes the trade-off concrete.
| Dimension | Direct provider connections | OmniRoute gateway |
|---|---|---|
| Configuration | Each agent configured separately per provider, with its own SDK and auth | One endpoint for every agent; providers configured once in the gateway |
| Rate limits | Agent stops or errors when a provider's quota runs out | Quota-aware routing falls back to another provider with capacity |
| Cost control | Usually solved by paying for higher tiers | Free tiers pooled across providers, plus token compression on paid traffic |
| Failure handling | Whatever retry logic each tool ships with | Circuit breakers, per-key cooldowns, and per-model lockouts |
| Credential exposure | Keys stored in each tool's config | Keys concentrated in one gateway, which must be secured and trusted |
| Operational burden | Little to run, but more to reconfigure | Another service to deploy, pin, monitor, and update |
The biggest difference is where complexity lives. With direct connections, complexity is spread across every tool's configuration, and failures surface as interrupted sessions. With a gateway, that complexity is concentrated in one place that you have to operate well. For a single developer using one agent with one paid plan, direct connections are simpler and perfectly adequate. Once several agents run in parallel, or a team shares capacity, the gateway's routing and failover start paying for the extra moving part.
Credentials deserve particular attention. Concentrating every provider key in one service reduces the number of places secrets live, which is good, but it also makes that service a high-value target. The security pipeline OmniRoute documents helps, and self-hosting keeps the keys on infrastructure you control. Using the hosted endpoint moves those keys to someone else's servers, which is a different calculation from either direct connections or self-hosting.
Finally, the cost comparison depends on how you use it. Free-tier pooling is most valuable for prototyping and personal work. For commercial workloads, the savings come more from compression and from routing cheaper tasks to cheaper models than from free quota, and each provider's terms set limits on what pooling is allowed.
Benefits of OmniRoute
For the people it targets, the gateway removes a set of everyday frictions. These are the benefits that show up in practice.
Sessions that don't die at a rate limit
The headline benefit is continuity. When one provider's quota runs out, the gateway routes the next request elsewhere instead of returning an error to the agent. A long refactor or test-writing session keeps going, and you avoid the lost context and half-applied changes that come from an agent stopping mid-task. For anyone running several agents at once, that alone can justify the setup. It also removes the habit of watching quota dashboards and manually switching keys whenever a session looks likely to run long.
One configuration for every tool
Claude Code, Codex, Cursor, Cline, and similar tools can all point at the same endpoint. Adding a provider, rotating a key, or changing routing happens once in the gateway rather than in every tool's settings. That consolidation makes experimenting with new providers or models far less tedious, and it keeps the configuration of individual tools simple. When a teammate joins, they point their tools at one address instead of collecting a dozen keys.
Lower spend on metered traffic
The compression pipeline reduces the tokens sent to providers that bill by usage, and routing strategies can send simpler requests to cheaper models. Combined with pooled free tiers for personal and prototype work, the gateway can stretch a budget considerably further than paying for top-tier plans everywhere. The actual saving depends on your workloads, so it is worth measuring rather than assuming.
Failures contained to the smallest scope
The three-layer failure model means a single bad key or a single unavailable model doesn't knock out a whole provider. Circuit breakers, cooldowns, and per-model lockouts each act on a different level. In practice, that produces fewer spurious fallbacks and more predictable behaviour than a simple global retry loop.
Security controls in the request path
Because all traffic passes through one pipeline, controls such as PII masking, prompt-injection detection, scoped tokens, and rate limiting apply uniformly. That is harder to achieve when each agent talks to providers directly with its own configuration, and it gives a team one place to enforce policy.
OmniRoute Use Cases
The gateway fits a few specific situations well. These are the ones its design points to most directly.
Running several coding agents in parallel
Developers who keep multiple Claude Code, Codex, or Cursor sessions running at once hit provider limits fastest. Pointing all of them at a single gateway lets quota-aware routing spread the load across providers and fall back when one is exhausted. The outcome is fewer interrupted sessions and less time spent switching keys or waiting for limits to reset. Because routing decisions are logged, it also becomes clear which providers are carrying most of the load.
Prototyping on free tiers
For side projects, experiments, and early prototypes, stacking the free tiers of several providers extends how much work can be done before paying for anything. The gateway tracks which pools still have capacity and routes accordingly. This is where free-tier aggregation is most clearly useful, provided each provider's terms permit the way you are using it.
A shared gateway for a small team
A team can self-host one gateway, configure providers and routing once, and give each developer a scoped token. Credentials stay in one controlled place, usage can be observed centrally, and team members don't each need their own collection of provider accounts. The remote CLI mode supports managing that shared instance from different machines.
Comparing providers and models
Because switching providers is a routing change rather than a reconfiguration of every tool, the gateway makes it easy to send similar tasks to different models and compare cost, latency, and quality. Teams deciding which models to standardise on can gather that evidence from real work instead of synthetic tests. Routing strategies can then encode what they learn, sending each kind of task to the model that handled it best for the price.
Always-on personal setups across devices
The range of deployment targets, including Docker on ARM boards, desktop apps, and Android via Termux, suits developers who want one gateway available wherever they work. A small always-on device can host the gateway at home, with laptops and other machines connecting to it remotely. Configuration and quota tracking then live in one place instead of drifting apart on each device.
OmniRoute Best Practices
These practices reflect how to adopt the gateway without creating new risks along the way.
- If rate limits are the actual bottleneck, not raw model capability, this addresses that directly — quota-aware failover across many providers is a real answer to "my agent stopped working because I hit a limit mid-task."
- The free-tier aggregation is genuinely useful for prototyping and personal use, where stacking multiple providers' free quotas meaningfully extends how much you can do before paying for anything.
- For production or team use, self-hosting is the more defensible default given the credential-proxying nature of the tool — evaluate it the way you would any gateway sitting in front of API keys, not as a drop-in convenience layer.
- Read each provider's terms before stacking free tiers. Aggregating legitimately available free quota is one thing; some providers restrict multiple accounts, automated use, or particular workloads on free plans. Check that the way you use each pool is within its terms, especially for anything commercial.
- Gateways need observability like any other production dependency. If agent traffic now flows through a single proxy, its latency, error rates, and routing decisions belong in the same LLM observability setup as the rest of your stack.
- This is an extremely fast-moving project. Release notes show hundreds of commits and PRs per cycle — a sign of real, active engineering, but also a reason to pin versions deliberately rather than tracking the latest release blind in anything you depend on.
- Test compression on your own workloads. Compression saves tokens, but aggressive settings can drop context an agent needs. Compare outputs with compression on and off for representative tasks before applying it widely, and use the per-request controls to tune it. Different tasks tolerate compression very differently, so one global setting rarely suits them all.
Common OmniRoute Mistakes
Most problems with a gateway like this come from treating it as a convenience layer rather than as infrastructure that handles credentials.
Defaulting to the hosted endpoint for team work
The hosted endpoint is the quickest way to try the tool, so it often becomes the permanent setup. For personal experiments that may be fine, but for team or commercial use it routes prompts and provider keys through infrastructure you don't control. Make the hosted-versus-self-hosted decision deliberately, and self-host for anything you wouldn't want to depend on a third party's trust model for.
Stacking free tiers without reading the terms
Free tiers come with conditions. Some providers restrict multiple accounts, automated use, or commercial workloads on free plans. Pooling quota in a way that breaks those conditions can get accounts suspended at the worst moment. Check each provider's terms for how you plan to use it, especially if the work is for a business.
Tracking the latest release in daily work
The project moves quickly, with many changes per release. Updating automatically means a routing or compression change can alter agent behaviour without warning. Pin a version, read release notes before upgrading, and test upgrades on a non-critical setup first.
Running the gateway without monitoring
Once every agent depends on the gateway, its failures become everyone's failures. Teams that don't track its latency, error rates, and routing decisions find out about problems from frustrated developers rather than from alerts. Add it to your observability stack like any other production dependency.
Leaving remote access too open
Remote CLI mode and scoped tokens are powerful. Issuing admin-scope tokens to every machine, or exposing the gateway on a public address without care, turns a convenience into a security risk. Give each machine the narrowest scope it needs and keep administrative access limited.
Practical Takeaway
OmniRoute is solving a real, specific pain point — provider rate limits and the tedium of manually juggling free tiers across a growing list of AI coding tools — with a level of routing and security engineering that goes well beyond a simple proxy script. The open question for any team isn't whether the tool works, it's whether the hosted convenience is worth the trust trade-off versus self-hosting a MIT-licensed, security-conscious gateway you can actually audit. For teams building on LLM APIs at any real scale, that's a decision worth making explicitly rather than defaulting into.
Teams evaluating gateway and routing architecture for AI coding tools — including the self-host-versus-hosted trade-off — can get hands-on help from Woyce Technologies.
FAQ
What is OmniRoute?
OmniRoute is an open-source AI gateway that routes requests from coding agents like Claude Code, Codex, and Cursor across 290+ AI providers, aggregating free-tier quota and automatically falling back to another provider when one runs out of capacity. It exists to stop agents from hitting a rate limit halfway through a task, which can cost you the session's context and leave a half-applied change to untangle.
Is OmniRoute free to use?
The software itself is MIT-licensed and free, self-hostable at no cost. It also aggregates the documented free tiers of many AI providers, though the specific free capacity available depends on those providers' own terms and can change over time. Some providers restrict multiple accounts or automated use on free plans, so read each provider's terms before stacking them, especially for commercial work.
Should I self-host OmniRoute or use the hosted version?
For anything beyond casual personal use, self-hosting is the safer default, since the tool sits in front of your API credentials and agent traffic. The hosted endpoint is faster to start with but means routing that traffic through third-party infrastructure rather than servers you control. Treat it like any proxy in front of API keys and self-host for production or team use.
Does OmniRoute work with Claude Code and Cursor?
Yes — it's designed to front tools including Claude Code, Codex, Cursor, Cline, and GitHub Copilot as a single gateway endpoint they can be pointed at instead of configuring each provider separately. It speaks the API shapes those tools already expect, so setup is usually a matter of changing the base URL and key in the tool's configuration. The CLI also includes a configure command for tools such as Codex, which helps if you are switching several agents over at once.
What is the token compression feature in OmniRoute?
OmniRoute applies a layered compression technique to reduce token usage on requests passing through the gateway, which lowers cost on any provider you're paying for by usage. Under the hood it is a twelve-engine pipeline that includes RTK, Caveman, and LLMLingua-2 running as a small ONNX model, with output styles and an adaptive dial to control how aggressive compression is per request. As with any compression, test it on your own workloads, since overly aggressive settings can remove context an agent actually needs.
Does OmniRoute support MCP?
Yes — it exposes an MCP-compatible interface as well as agent-to-agent (A2A) protocol support, so it can integrate with existing agent tooling rather than requiring a custom integration layer. In practice that means an agent setup already built around MCP can treat the gateway as one more endpoint, while A2A support covers cases where several agents need to coordinate through the same routing layer.
What routing strategies does OmniRoute support?
Nineteen, covering different priorities: simple ones like priority order and round-robin, cost-aware strategies like cost-optimized (minimize price per request) and headroom (prefer the provider with the most remaining quota), and latency-aware options like power-of-two-choices load balancing. They can be mixed per step inside a routing "combo," or you can skip configuration entirely and use one of the built-in auto variants (auto/coding, auto/fast, auto/cheap, and others) that score connected providers live.
Does OmniRoute have a command-line interface?
Yes — beyond the HTTP gateway, it ships a CLI (omniroute, omniroute chat, omniroute setup, omniroute doctor) plus a remote mode that lets you control a gateway running on another machine using scoped access tokens. Those tokens can be minted with read, write, or admin scope for different machines, and process-spawning routes stay loopback-only however the CLI is connected, which limits what a misconfigured remote setup could do.
Can OmniRoute run on a Raspberry Pi or a phone?
Yes. It has native ARM64 support for Raspberry Pi and ARM servers, and it runs on Android through Termux without root access. It's also installable as a PWA and as a Docker image built for both AMD64 and ARM64. That range matters most if you want one gateway instance available across several machines without standing up separate infrastructure for each.
How does OmniRoute handle a provider failing mid-request?
Through three separate layers rather than one retry loop: a provider-level circuit breaker that trips on repeated 5xx/408 errors and reroutes to the next provider, a connection-level cooldown for a single failing key with exponential backoff, and a per-model lockout that blocks just one failing model without dropping the whole provider connection.
Conclusion
Rate limits are one of the most common reasons AI coding agents stall, and juggling free tiers across many providers by hand does not scale past a single developer. OmniRoute tackles that with a single gateway endpoint that understands the API shapes coding tools already use, routes across a very large set of providers with quota awareness, and handles failures at the provider, connection, and model level rather than with one blunt retry loop.
What stands out is the engineering depth for a tool in this category: a real CLI with remote control and scoped tokens, broad deployment options, a multi-engine compression pipeline, and a documented security model with guardrails, signed keys, and CI security scanning.
The caveats matter as much as the features. A gateway sees your prompts and credentials, so the hosted endpoint is a trust decision, and self-hosting is the safer default for team or production use. Free-tier stacking must stay within each provider's terms, the project moves quickly enough that versions should be pinned, and compression should be tested against your own workloads. Teams evaluating gateway and routing architecture for AI coding tools can start by self-hosting a pinned version for one team and comparing cost and failure rates over a month. If you want help designing that routing layer, talk to our LLM integration team.