

Not every widely-starred open-source project is something a business should reach for, and MediaCrawler is the clearest example we've covered so far. It's a genuinely popular tool — over 61,000 GitHub stars — for pulling posts, comments, and creator data from Xiaohongshu (RED), Douyin, Kuaishou, Bilibili, Weibo, Baidu Tieba, and Zhihu. It's also a tool whose own maintainer explicitly restricts it to learning and research use, prohibits commercial use in its license terms, and links directly to a public repository of web-scraping legal cases in China as a warning to anyone considering using it otherwise. That combination — real technical popularity and an explicit "don't build a business on this" disclaimer from the author — is worth understanding in detail before any team gets curious about it.
Below we cover how MediaCrawler's login-state technique works, what running it involves, what it collects, what its license and disclaimer actually say, who legitimately uses it, a compliance checklist to run before adopting any social-data scraper, and the licensed alternatives that meet the same business need.
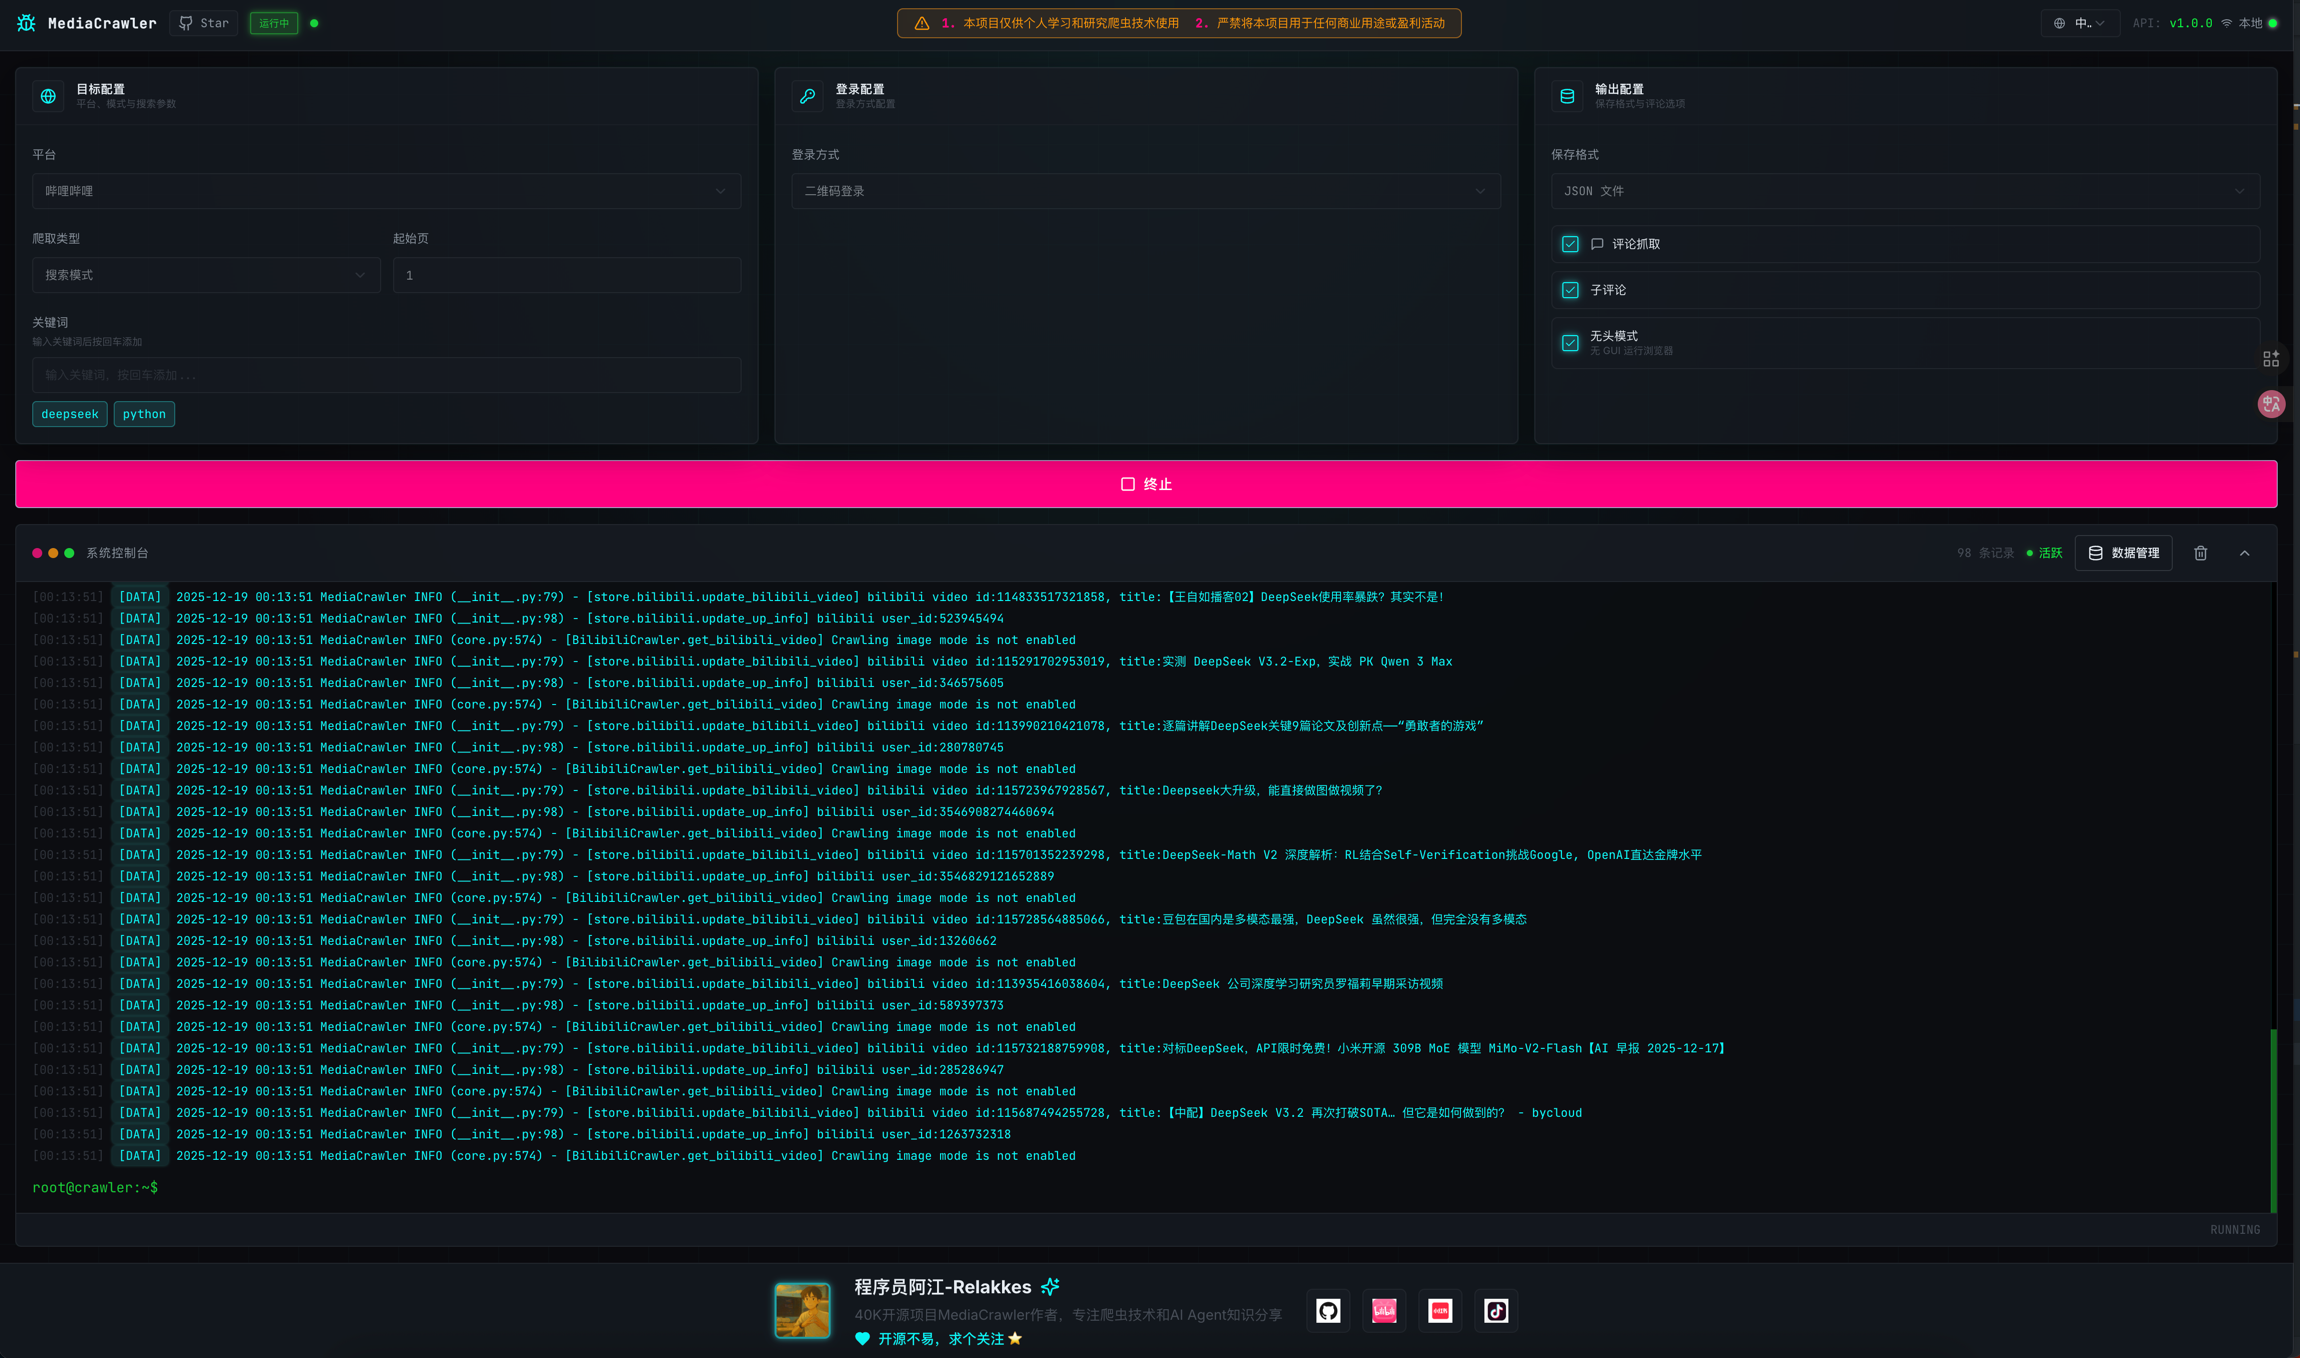
How It Actually Works
The technical premise is genuinely clever, and it's worth understanding on its own terms. Most social platforms protect their APIs with signed requests — every call includes a cryptographic signature generated by obfuscated, frequently-changing JavaScript running in the browser. The traditional way to scrape a platform like this is to reverse-engineer that JavaScript: painstaking, breaks every time the platform ships an update, and is the main reason building a reliable scraper for a major social app is a real engineering project rather than a weekend script.
MediaCrawler sidesteps that entirely. It uses Playwright to drive a real browser, logs in once, and saves that authenticated browser context. From then on, it doesn't need to know how the signature algorithm works — it just asks the real, already-logged-in browser page to generate a valid signature for it via a JS expression, the same way the platform's own frontend would. No cryptography to reverse, no algorithm to keep re-breaking after every platform update. That's the core insight, and it's the reason the project has stayed viable across years of anti-bot changes on the platforms it targets, while algorithm-reversing scrapers tend to break constantly.

What Actually Running It Looks Like
The setup is more involved than a typical scraper library, and the friction itself is informative. It expects uv for Python dependency management, Node.js 16 or newer (Douyin and Zhihu specifically need it), and — in its default configuration — a real, already-installed Chrome browser (version 144 or newer) running with remote debugging enabled on port 9222. That last part is the more interesting design choice: rather than launching a fresh, unmarked Playwright browser instance from scratch, the default mode connects to Chrome over the Chrome DevTools Protocol and rides on the browser's existing cookies, login state, and extensions. The project's own docs frame this directly as a way to reduce the platform's risk-control detection, since a browser with real history and a real profile behind it doesn't look like a bot the way a bare automation instance does. A standard Playwright-only mode is available as a fallback via a config flag, but CDP-against-real-Chrome is the path the project steers users toward.
Once running, collected data can land in CSV, JSON, JSONL, Excel, SQLite, or MySQL — a broader set of output targets than most single-purpose scrapers bother supporting, which again points toward the project's stated identity as something to study the architecture of, not just run.
What It Actually Covers
The feature set is broad and consistent across all seven supported platforms: keyword search, scraping a specific post by ID, pulling nested (secondary) comments, scraping a creator's full homepage, reusing cached login sessions across runs, routing traffic through an IP proxy pool, and generating a word-cloud visualization from collected comments. A separate closed-source "Pro" version, sold by the same author, adds resume-on-failure, multi-account rotation, and removes the Playwright dependency entirely — which tells you plainly where the maintainer draws the line between the free educational tool and something built for sustained, larger-scale operation.
Benefits of MediaCrawler's Design, for Learning
The license limits what you should do with MediaCrawler, but it does not make the engineering less instructive. For developers and researchers studying scraping architecture, these are the parts worth understanding. None of them requires running the tool against a live platform; reading the code and documentation is enough to learn from each.
Resilience Without Reverse Engineering
Most scrapers for signed-request platforms depend on a reverse-engineered copy of the platform's signing code, which breaks whenever the platform ships an update. Delegating signature generation to a real logged-in browser removes that dependency. It is a clear lesson in designing around a moving target: instead of copying the logic that keeps changing, reuse the component that is always current.
One Pattern Across Seven Platforms
The same feature set (keyword search, post lookup, nested comments, creator pages, cached sessions, proxy routing) runs across seven quite different platforms. Studying how the project keeps a consistent interface while each platform has its own quirks is useful for anyone designing connectors or adapters, whatever the data source, from internal systems to public APIs.
Flexible, Well-Separated Output
Collected data can be written to CSV, JSON, JSONL, Excel, SQLite, or MySQL. Separating collection from storage this cleanly is good practice in any data pipeline, and the project shows a straightforward way to do it so the same crawl can feed a quick analysis or a database without changes to the collection logic.
A Concrete View of How Platforms Detect Bots
The project's documentation explains why a real Chrome profile with history and extensions looks different from a fresh automation instance. For security teams and platform engineers, that is a practical illustration of the signals anti-bot systems rely on, and of why fingerprinting is an arms race.
A Built-In Lesson in Licensing
Few repositories state their legal limits as plainly. Reading the disclaimer alongside the code is a good reminder for any team that "open source" and "free for commercial use" are separate questions, and that a dependency's license deserves a review before its code does. The same applies to every package in a data pipeline, not only the obvious scrapers.
The Part That Actually Matters: Read the License
This is the section that matters more than the architecture, and it's worth being direct about it rather than treating it as a footnote.
MediaCrawler's own README states, in its own disclaimer, that the project exists strictly as "a technical research and learning tool," that it is "strictly prohibited from being used for any illegal purposes or non-learning, non-research commercial activities," and that users bear full legal responsibility for how they use it. It specifically calls out compliance with China's Cybersecurity Law, and even references its Counter-Espionage Law, as laws a user needs to consider — language you don't see attached to a typical open-source scraping library, and a strong signal about how seriously the maintainer takes the legal exposure here. The README also links directly to a public collection of real criminal and civil web-scraping cases in China as a cautionary reference.
None of the platforms MediaCrawler targets permit this kind of access in their terms of service. Scraping a platform that requires a login, using a saved session to keep bypassing anti-bot protections, and extracting user-generated content and comments at scale runs directly against the terms nearly every major social platform enforces — and increasingly, against data protection law wherever the platform's users are located, since comments and profile data are personal data under most modern privacy regimes. A tool being popular and technically well-built does not change what a target platform's terms of service, or applicable law, actually say.
MediaCrawler Use Cases
Understanding the real use cases helps separate the legitimate motivations from the risky ones. The first three fit the project's own framing; the last is the one that pulls businesses in, and the one its license rules out.
Academic and Independent Research
Studying platform dynamics, discourse patterns, or misinformation spread on Chinese social platforms, where the project's own "learning and research" framing genuinely applies. Researchers face a real gap: official APIs rarely expose the comment threads and cross-platform data that discourse studies need. Even here, the research still has to meet the platform's terms, data protection law, and the institution's ethics review, so the license framing is a starting point rather than a clearance.
Personal Projects and Technical Learning
The project is explicitly positioned, including by its own author, as a way to study browser-automation-based scraping architecture — a legitimate reason to read the code even if you'd never run it against a live account. Developers learning Playwright, the Chrome DevTools Protocol, or how request signing works on modern web apps can learn a great deal from how the code is organised, without collecting anyone's data or logging into a real account.
Security and Compliance Reviews
Security, legal, and data-governance teams study tools like MediaCrawler so they can recognise them. Knowing what login-state reuse, CDP connections to a real browser, and proxy pools look like in code or network traffic helps a review catch a risky scraping dependency before it reaches production. The outcome is a clearer policy on which data-collection tools are allowed, and why, applied consistently across teams.
Social Listening and Brand Monitoring: The Risky One
This is the use case that pulls businesses toward tools like this, and it's exactly the use case the project's license prohibits. Wanting to track brand mentions or competitor activity on Xiaohongshu or Douyin is a completely reasonable business need; using an unlicensed scraper explicitly marked "non-commercial use prohibited" to do it is not the way to meet that need. The licensed routes described next cost more and cover less, but they are the ones a business can defend.
What to Use Instead for Business Needs
If the actual goal is social listening, competitive monitoring, or campaign measurement on Chinese platforms, there are paths that don't carry MediaCrawler's legal exposure:
- Official platform APIs and creator/business tooling. Douyin, Xiaohongshu, and Weibo all offer business-facing APIs and ad-platform data access for verified accounts — more limited than a scraper, but licensed and stable.
- Licensed social-listening vendors. Commercial social-listening and market-intelligence platforms that specifically cover the Chinese social landscape maintain their own compliant data agreements with the platforms, which is exactly the operational overhead a scraper is trying to skip — legitimately, in this case.
- A general-purpose, ToS-respecting scraping API for anything outside login-gated social platforms. For public, non-authenticated web content, a tool like Firecrawl is a meaningfully different risk profile — it isn't designed around defeating login-gated anti-bot protections on specific platforms, and it defaults to respecting
robots.txt.

MediaCrawler vs Licensed Social Data Access
The real choice for a business is not between scrapers, but between scraping and licensed access. Here is how MediaCrawler compares with the alternatives described above.
| Dimension | MediaCrawler | Official platform APIs | Licensed social-listening vendor |
|---|---|---|---|
| Permitted for commercial use | No, license restricts to learning and research | Yes, within the platform's API terms | Yes, under the vendor's data agreements |
| Platform terms of service | Runs against them for login-gated scraping | Compliant by design | Vendor maintains compliant access |
| Data coverage | Broad: posts, nested comments, creator pages | Narrower, limited to what the API exposes | Broad across platforms, aggregated |
| Stability | Depends on sessions, proxies, and anti-bot changes | Stable, versioned interfaces | Stable, vendor absorbs platform changes |
| Personal data handling | Entirely on the user | Shared with the platform's rules | Vendor provides some controls; you still have obligations |
| Cost | Free software, high legal and operational risk | Usually low, sometimes requires verified business accounts | Subscription fees |
The table shows why MediaCrawler appeals: it covers more data than official APIs and costs nothing in licence fees. But those advantages come entirely from doing what the platforms and the project's own license prohibit. Coverage that depends on reusing logged-in sessions to bypass protections is coverage a business cannot rely on, legally or operationally, because it can disappear with the next anti-bot change or a single enforcement action.
Official APIs sit at the other end. They expose less, particularly around comments and other users' content, but they are stable and sanctioned. For campaign measurement and monitoring a brand's own accounts, they often cover most of what is needed.
Licensed vendors fill the gap between the two. They aggregate broader data across platforms under agreements they maintain, which is the compliance work a scraper skips. For ongoing social listening on Chinese platforms, this is usually the practical choice, with official APIs alongside for first-party data.
Common Social Media Scraping Mistakes
The risks around tools like MediaCrawler usually enter a business through a handful of avoidable decisions, often made by a well-meaning analyst or developer trying to answer a reasonable business question quickly.
Treating GitHub Stars as an Endorsement
A project with tens of thousands of stars feels safe to adopt. Stars measure interest, not legal fitness. MediaCrawler is popular precisely because it is technically effective, and that says nothing about whether a business may use it. Review the license and disclaimer before the code.
Assuming Visible Means Free to Collect
Content that any logged-in user can see is not automatically content a company may collect, store, and analyse at scale. Platform terms restrict automated access, and comments and profile details are personal data under most privacy laws, regardless of who could view them.
Running Scrapers on Employee or Personal Accounts
Logging in with a staff member's account to power a crawl ties the activity to a real person and the company. If the platform takes action, or the activity is challenged legally, both carry the consequences. It also often breaches the platform's terms for that account.
Collecting First, Deciding on Purpose Later
Pulling everything available and working out the use afterwards leaves a store of personal data with no lawful basis, no retention limit, and no clear owner. Under GDPR, PIPL, or the DPDP Act, that is a liability in itself, whatever tool collected it.
Letting a Prototype Become the Pipeline
A scraper used once for a quick analysis has a way of becoming a scheduled job feeding a dashboard. By then it is a production dependency nobody approved. Flag scraping tools in code review and dependency audits so they get a decision, not an accident. A short list of approved data sources makes this easier for everyone.
Social-Data Scraping Best Practices: A Compliance Checklist
MediaCrawler is an extreme case because its own author says not to use it commercially, but the same questions apply to any tool that collects data from social platforms. Treat the checklist as a gate that every data-collection tool passes through, not a one-off exercise, and record the outcome. Before anything reaches a production pipeline, work through these steps:
- Read the tool's license and disclaimer. Non-commercial, research-only, or "no warranty of legality" terms are a decision in themselves. Open source does not mean free for any use.
- Read the target platform's terms of service. Check whether automated access, logged-in scraping, and storage of user content are permitted, and whether an official API covers the same data.
- Classify the data. Comments, usernames, and profile details are personal data under most privacy regimes, including the EU's GDPR, China's Personal Information Protection Law, and India's DPDP Act. Identify which laws apply based on where users are located, not just where your company is.
- Establish a lawful basis and a retention limit. Document why you need the data, what you'll keep, and when it gets deleted.
- Avoid techniques designed to evade protections. Session reuse to bypass anti-bot systems, proxy pools to avoid rate limits, and account rotation all increase legal exposure and are hard to defend in a dispute.
- Get a legal and security sign-off. Treat scraping dependencies like any other third-party risk, with a named owner and a review date.
- Prefer licensed access where it exists. If an official API or a licensed data vendor meets 80% of the need, the remaining 20% rarely justifies the risk.
For public web pages rather than login-gated platforms, the IETF's robots.txt standard (RFC 9309) describes how sites signal what automated crawlers may access, and respecting it is the baseline for responsible crawling.

Practical Takeaway
MediaCrawler is worth knowing about as a genuinely interesting piece of engineering — the login-state-reuse trick is a smart way to sidestep a real technical problem, and it's a large part of why the project has stayed relevant. But it's a case where the right business takeaway isn't "how do we use this," it's "this exists, it's popular, and it's exactly the kind of dependency a legal or security review should catch before it ends up in a production pipeline." Any team whose roadmap involves social data at scale should be having the compliance conversation — API access agreements, data protection obligations under regimes like India's DPDP Act or the EU framework — before evaluating any specific tool, not after.
Teams building AI-driven marketing or social monitoring tooling who need a compliant data pipeline — official APIs, licensed data partnerships, or scraping architecture that actually respects target platforms' terms — can get hands-on architecture help from Woyce Technologies.
FAQ
What is MediaCrawler?
MediaCrawler is an open-source Python tool that scrapes posts, comments, and creator data from Chinese social media platforms — including Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Baidu Tieba, and Zhihu — using a saved, logged-in browser session to avoid reverse-engineering each platform's request-signing algorithm. It has a large following on GitHub and is often studied as an example of browser-automation scraping architecture, but its own maintainer restricts it to learning and research use and prohibits commercial use.
Is it legal to use MediaCrawler?
The project's own license and disclaimer restrict it to non-commercial learning and research use, and its README explicitly warns about legal risk under Chinese law, including citing web-scraping criminal cases. Scraping login-gated social platforms also typically violates those platforms' terms of service regardless of jurisdiction. It is not a tool a business should deploy for commercial data collection.
Can I use MediaCrawler for business social listening?
No — that use case is specifically what the project's license prohibits. Businesses that need social listening or brand monitoring on Chinese platforms should use official platform APIs or licensed social-listening vendors instead. Beyond the license itself, collecting comments and profile data at scale raises personal-data obligations and terms-of-service violations that a business would have to answer for. Licensed routes cost more up front but remove that exposure and tend to be far more stable over time.
How is MediaCrawler technically different from a typical scraper?
Instead of reverse-engineering each platform's cryptographic request-signing algorithm — which breaks every time the platform updates it — it drives a real logged-in browser session via Playwright and asks that authenticated session to generate valid signatures directly, sidestepping the reverse-engineering problem entirely. Traditional scrapers break whenever a platform changes its obfuscated JavaScript, so this approach has stayed working across platform updates. The same property is what makes it legally sensitive: it relies on an authenticated session to keep accessing data the platform restricts.
Is MediaCrawler the same as Firecrawl?
No. Firecrawl is a general-purpose web scraping API aimed at public, non-authenticated content, built for commercial and AI-agent use, and defaults to respecting robots.txt. MediaCrawler is purpose-built to access specific login-gated social platforms and is explicitly licensed for non-commercial research use only — a fundamentally different risk profile. If you need public web content for an AI pipeline, Firecrawl is the closer fit, while MediaCrawler's licence alone rules it out for commercial work.
What should a business do instead of using tools like this?
Use each platform's official business or developer API, or work with a licensed social-listening or market-intelligence vendor that maintains compliant data-access agreements with the platforms directly. The compliance and legal review that a scraper skips is exactly what those paths are paying for. Before choosing any route, document what data you need, why, how long you'll keep it, and which privacy laws apply to the users involved. That brief makes vendor and API conversations much faster.
What does MediaCrawler need installed to actually run?
The uv Python package manager, Node.js 16 or newer for the Douyin and Zhihu crawlers specifically, and — in its default configuration — a real installation of Chrome (version 144+) running with remote debugging enabled, since the default mode connects to an existing Chrome session over the Chrome DevTools Protocol rather than launching a fresh automated browser.
Why does MediaCrawler connect to an existing Chrome browser instead of launching its own?
Its own documentation frames this as a way to reduce a platform's bot-detection risk: a browser carrying real cookies, login history, and extensions doesn't present the same fingerprint as a bare, freshly-launched automation instance. A standard, self-launched Playwright mode exists as a fallback via a config setting. That design matters for risk, because techniques built to evade a platform's protections, such as session reuse, increase legal exposure and are hard to defend in a dispute.
Where can MediaCrawler save the data it collects?
CSV, JSON, JSONL, Excel, SQLite, or MySQL — a wider set of storage targets than most single-purpose scraping tools support. Whatever the format, stored comments and profile details remain personal data. Any organization holding it takes on obligations around security, retention, and deletion under privacy law, which is easy to forget once data sits in a local database.
What's the difference between MediaCrawler and MediaCrawlerPro?
MediaCrawlerPro is a separate, closed-source, paid product by the same author. It adds resume-on-failure crawling, multi-account and IP-proxy-pool rotation, drops the Playwright dependency entirely, and is pitched partly as a better architecture to study — but it doesn't change the underlying licensing risk of scraping these platforms commercially, since it's a different product with its own terms.
Conclusion
MediaCrawler shows that GitHub popularity and fitness for business use are different questions. Its core technique, letting a real logged-in browser generate platform signatures instead of reverse-engineering them, is clever and explains why the project keeps working when other scrapers break. But its maintainer restricts it to learning and research, prohibits commercial use, and points users to real scraping prosecutions in China.
For businesses, the issue goes beyond one license. Logged-in scraping of social platforms runs against their terms of service, and comments and profile data are personal data under most modern privacy laws. Techniques built to evade anti-bot systems make that harder to defend, not easier.
The legitimate need behind interest in tools like this, understanding what customers and competitors are saying on Xiaohongshu, Douyin, or Weibo, is real. It's better met through official business APIs and licensed social-listening vendors, or through ToS-respecting crawling for public web content.
Before any scraper enters your stack, run the compliance checklist above and get a legal review. If you need a social-data pipeline built on licensed sources and sound data handling, our technology consulting team can help you design it.